
Fine-Tune Llama 3.1 with Unsloth: 2x Faster
Fine-tuning large language models (LLMs) on educational or small datasets can be straightforward, but when it comes to commercial applications with long input sequences or large outputs, the challenge grows exponentially. Even with advanced techniques like QLoRA, you might still hit the limits of an 80 GB GPU (such as the H100 or A100) with just one training example. Moreover, fine-tuning with long input data can be frustratingly slow.
Fortunately, there's a solution that can save both time and resources: Unsloth. This post will introduce you to Unsloth, show you how to install and use it on GPU cloud platforms like Vast AI, MassedCompute, and RunPod, and share best practices that go beyond the official documentation.
What is Unsloth?
Unsloth is a free, open-source library licensed under Apache 2.0, designed for efficient LLM fine-tuning. It’s 2.2 times faster than the standard Huggingface Transformers library, uses 70% less GPU memory, and maintains accuracy with QLoRA (4-bit) and LoRA (16-bit) fine-tuning. Additionally, it doubles the speed of inference.
If this sounds too good to be true, rest assured: the field of LLM fine-tuning is still young and evolving, often resulting in inefficiencies. Unsloth addresses these inefficiencies, improving memory usage and training performance.
The library’s codebase is well-written and straightforward, allowing you to easily understand how it optimizes your model. Essentially, Unsloth eliminates unnecessary computations and harmonizes data types, delivering these impressive performance gains.
We’ve extensively used Unsloth in our projects, and this post reflects our experiences as of August 2024. As Unsloth is rapidly evolving, we recommend checking the official documentation for the latest updates if you’re reading this at a later date.
Installing Unsloth
Getting started with Unsloth can be a bit tricky, especially during installation. The process isn’t as straightforward as one might expect, and the most reliable way to set it up is by using a Conda environment.
In this guide, we\u2019ll demonstrate the installation using a MassedCompute H100 VM. However, these steps are also applicable to Docker-based GPU instances on platforms like Vast AI and RunPod.
1. Create the VM
First, head over to MassedCompute and create a new VM. In this example, we’re using an H100 spot instance to take advantage of lower pricing. However, keep in mind that spot instances can be terminated with just a one-hour notice, so plan accordingly if you choose this option.
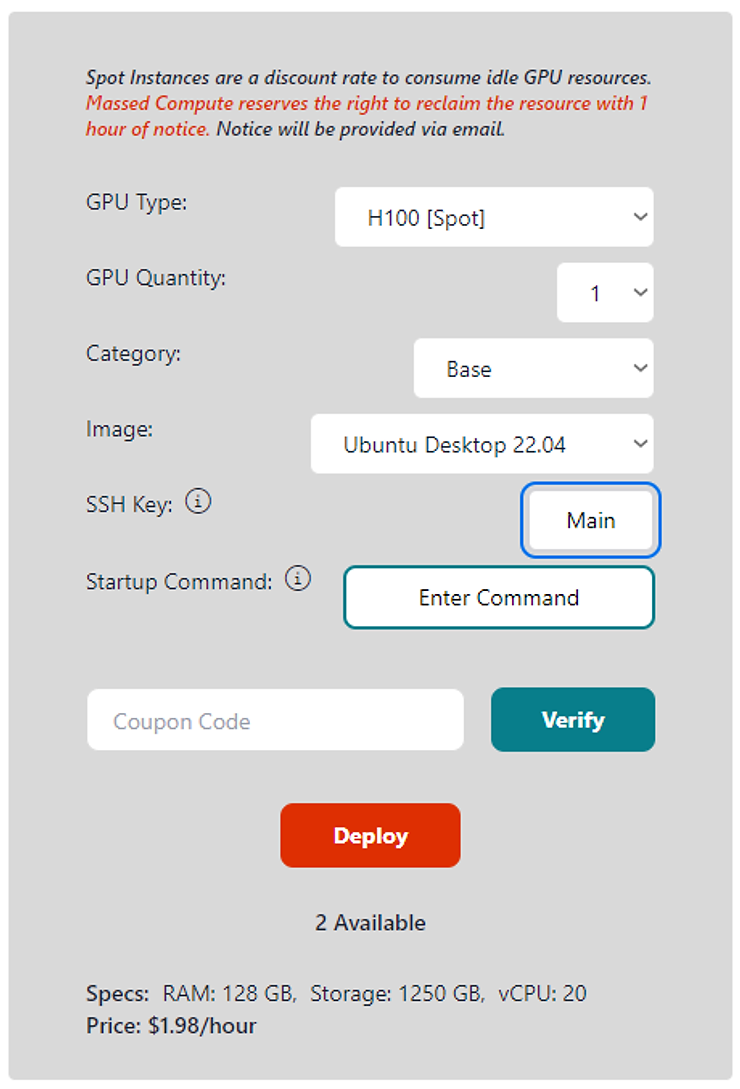
Select the "Base" instance type and the "Ubuntu Desktop 22.04" OS image, then click "Deploy."
2. Update Packages
Next, update the base packages, install the Huggingface CLI, and authenticate with your Huggingface token.
sudo apt update
sudo apt upgrade -y
sudo apt install python3-pip -y
python3 -m pip install --upgrade pip
pip3 install packaging huggingface_hub[cli]
export PATH=$PATH:~/.local/bin
huggingface-cli login --token hf_<YOUR HUGGINGFACE TOKEN>
3. Install Conda
mkdir -p /home/Ubuntu/miniconda3
wget https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh -O ~/miniconda3/miniconda.sh
bash /home/Ubuntu/miniconda3/miniconda.sh -b -u -p ~/miniconda3
rm -rf /home/Ubuntu/miniconda3/miniconda.sh
/home/Ubuntu/miniconda3/bin/conda init bash
. /home/Ubuntu/.bashrc
4. Create Conda Unsloth Environment
conda create --name unsloth_env python=3.10
conda activate unsloth_env
conda install pytorch==2.2.0 cudatoolkit torchvision torchaudio pytorch-cuda=12.1 -c pytorch -c nvidia
conda install xformers -c xformers
pip install bitsandbytes matplotlib datasets transformers trl peft accelerate sentencepiece
pip install --upgrade --force-reinstall --no-cache-dir git+https://github.com/unslothai/unsloth.git
If you’re using Weights & Biases, install it as well:
pip3 install wandb
wandb login
<YOUR WEIGHTS & BIASES TOKEN>
5. Install and Launch Jupyter Notebook
sudo apt-get install nano -y
pip3 install jupyter
jupyter notebook --generate-config
Edit the Jupyter config to set the IP address and port:
nano ~/.jupyter/jupyter_notebook_config.pyAdd the following lines after "c = get_config()":
# Set the IP address to '*'
c.NotebookApp.ip = '0.0.0.0'

# Set the port to 10000
c.NotebookApp.port = 10000

# Disable browser opening
c.NotebookApp.open_browser = False
Set your Jupyter Notebook password and start it:
jupyter notebook password
jupyter notebook --allow-root
Open your browser and go to http://<VM_IP_ADDRESS>:10000
Model Training
For training, we will use the Llama 3.1 8B training notebook from the official Unsloth GitHub repository.
1. Remove PIP Package Installation
Since we’ve already set up a fully functional Unsloth Conda environment, the first step is to remove the PIP package installation commands from the notebook.
2. Adjust the Prompt Structure for Llama 3.1
The original Unsloth notebook uses the Alpaca dataset and its corresponding prompt structure for demonstration purposes. To achieve the best results with the fine-tuned Llama 3.1 model, it’s crucial to use the exact prompt structure that the model was trained with.
The meta-llama/Meta-Llama-3.1-8B-Instruct model has the following prompt structure:
| Token | Description |
|---|---|
| <|begin_of_text|> | Specifies the start of the prompt |
| <|end_of_text|> | Model will cease to generate more tokens |
| <|start_header_id|> <|end_header_id|> | Enclose the role for a particular message (system, user, assistant, ipython) |
| <|eom_id|> | End of message – signals that a tool call needs to be made |
| <|eot_id|> | End of turn – signals the model has finished generating a response |
| <|python_tag|> | Special tag used in model’s response to signify a tool call |
Note that we do not add the <|begin_of_text|> token to our prompt structure because the tokenizer adds it automatically.
3. Train on Completion Only
During LLM training, there is a potential issue known as "overfitting on the input." This occurs because modern LLMs, being decoder-only models, learn the probability of each token based on all previous tokens, including those in the model’s input. As a result, if the same input appears multiple times in the training set, the model may learn that the input follows a specific structure.
To mitigate this problem, the Transformers library offers an option to train the model on the completion (the AI-generated response) only. In this mode, the model still generates both the input and the output, but the training process only updates the model based on the output, avoiding overfitting on the input.
To enable this mode, import DataCollatorForCompletionOnlyLM and configure it with the text pattern that identifies the response portion:
from trl import SFTTrainer, DataCollatorForCompletionOnlyLM

response_template = "<|start_header_id|>assistant<|end_header_id|>"
collator = DataCollatorForCompletionOnlyLM(response_template, tokenizer=tokenizer)
The training is completed in 1 min 39 sec. It requires 14.5 GB GPU memory.
4. Inference
While the Fibonacci sequence is a relatively simple task, it serves as a basic test of the model’s functionality. It’s important to note that the Alpaca dataset was likely part of the original training data for Llama 3.1. However, when you use your own proprietary dataset, the training process can significantly enhance the model’s performance, allowing it to handle more complex and specialized tasks effectively.
Please find the complete code for this tutorial in our Colab.
Limitations
While Unsloth offers a powerful solution to many challenges, the free version does have its limitations.
- The free version is only compatible with Unsloth-modified models. Although the Unsloth team works diligently to support the most popular and advanced models, more specialized or niche models may not yet benefit from Unsloth’s optimizations.
- Unsloth does not support multi-GPU training. If you hit the GPU memory limit, even with Unsloth’s memory-efficient training, you may need to explore alternative options, as there’s no way to distribute the load across multiple GPUs.
- Unsloth also provides out-of-the-box RoPE (Rotary Positional Encoding) scaling, which allows you to extend the context window beyond its original size. However, only a few models currently support RoPE scaling with Unsloth.
Conclusion
Developing your custom LLM could enhance data security and compliance and enable an AI competitive advantage for your product. Check out our other posts for more:
- Low-Rank Adaptation (LoRA) for Efficient Fine-Tuning of Large Language Models
- Why Do You Need an AI Strategy? AI as a Competitive Advantage
- AI Strategies That Offer a Sustainable Competitive Advantage
- Start with the Right AI Development Culture
Looking for Fast, Cost-Effective LLM Fine-Tuning?
Let's evaluate the best fine-tuning framework for your use case and build a custom model that gives you a competitive edge.