
Low-Rank Adaptation (LoRA) for Efficient LLMs
In the fast-evolving world of artificial intelligence, adapting large language models to new tasks or datasets efficiently is crucial. This blog post aims to demystify Low-Rank Adaptation (LoRA), a cutting-edge technique designed to fine-tune large language models like Llama-2, Llama-3, and Mistral. By the end of this article, you’ll understand what LoRA is, how it works, and why it’s becoming an essential tool for AI practitioners.
Why LoRA Matters
Traditional fine-tuning of large models can be both time-consuming and costly, often requiring substantial computational resources. LoRA introduces a novel approach that mitigates these issues by reducing the number of trainable parameters through low-rank matrix decomposition. This method not only speeds up the training process but also conserves memory, making it more feasible to deploy these models in various practical applications.
LoRA is particularly beneficial in scenarios where models need to be frequently updated or adapted to new tasks without the luxury of extensive computational power. By simplifying the adaptation process, LoRA enables more organizations to harness the power of large language models, democratizing access to advanced AI capabilities.
In the sections that follow, we will delve deeper into the mechanics of LoRA, explore its practical applications, and highlight some real-world case studies demonstrating its effectiveness. Whether you’re an AI researcher, data scientist, or machine learning engineer, understanding LoRA can significantly enhance your ability to work with large language models effectively.
What is LoRA?
LoRA is an innovative technique designed to reduce the number of trainable parameters in large language models. By focusing on this reduction, LoRA makes the fine-tuning process faster and more efficient without compromising the model’s performance. This method leverages mathematical principles to simplify and accelerate the adaptation of large models to new tasks or datasets.
Key Concepts:
- Low-Rank Decomposition: At the heart of LoRA is the concept of low-rank decomposition. This involves breaking down large matrices into smaller, more manageable pieces. By doing this, we can focus on the most critical parts of the data, making the training process more efficient. Essentially, low-rank decomposition helps in identifying and isolating the most influential parameters that need adjustment during fine-tuning.
- Matrix Rank: The rank of a matrix is a measure of its complexity, determined by the number of linearly independent rows or columns it contains. In the context of LoRA, we aim to use matrices with lower ranks to represent changes in the model’s weights. This approach significantly reduces the computational load, as lower-rank matrices are simpler and require fewer resources to process.
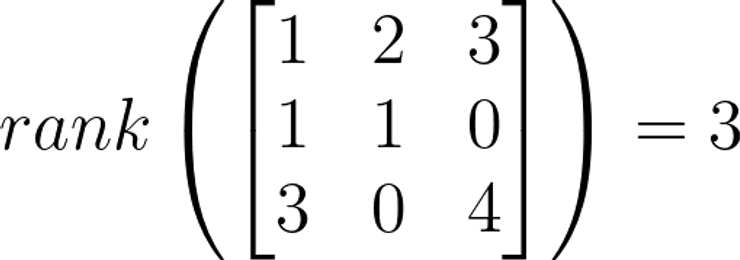
Full-Rank Matrix (by ML6)
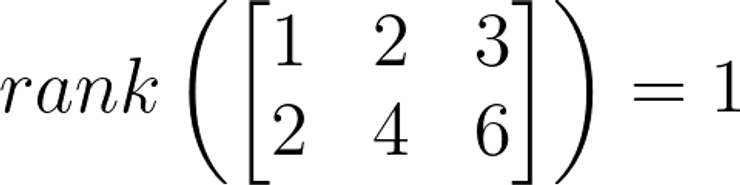
Rank-Deficient Matrix (by ML6)
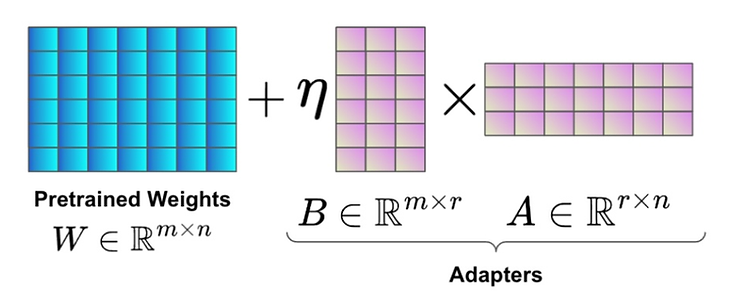
Weight reparametrization with LoRA adapters (by Wang et al.)
Benefits:
- Faster Training Times: By reducing the number of trainable parameters, LoRA speeds up the training process. This is particularly beneficial when working with large datasets or when rapid model updates are needed.
- Reduced Memory Usage: LoRA’s efficiency extends to memory usage as well. Smaller parameter sets require less memory, making it possible to train and fine-tune large models on hardware with more modest specifications.
- Easier Model Storage and Sharing: Models fine-tuned with LoRA have smaller weight files, making them easier to store and share. This is particularly useful for collaborative projects or when deploying models across different platforms.
How LoRA Works
When adapting large models with LoRA, we update the weight matrices using low-rank matrices. Instead of modifying the entire weight matrix directly, LoRA introduces two smaller matrices that, when multiplied together, approximate the changes needed in the original matrix. This method not only simplifies the computations but also preserves the essential features of the model while adapting it to new tasks or datasets.
Key Parameters:
- rank: Defines the inner dimension of the low-rank matrices. A higher rank means more trainable parameters.
- lora_alpha: A scaling factor for the low-rank matrices. It adjusts the influence of the low-rank adaptation on the overall model.
- target_modules: Specifies which parts of the model will use LoRA. This allows for targeted fine-tuning and helps in reducing unnecessary computations.
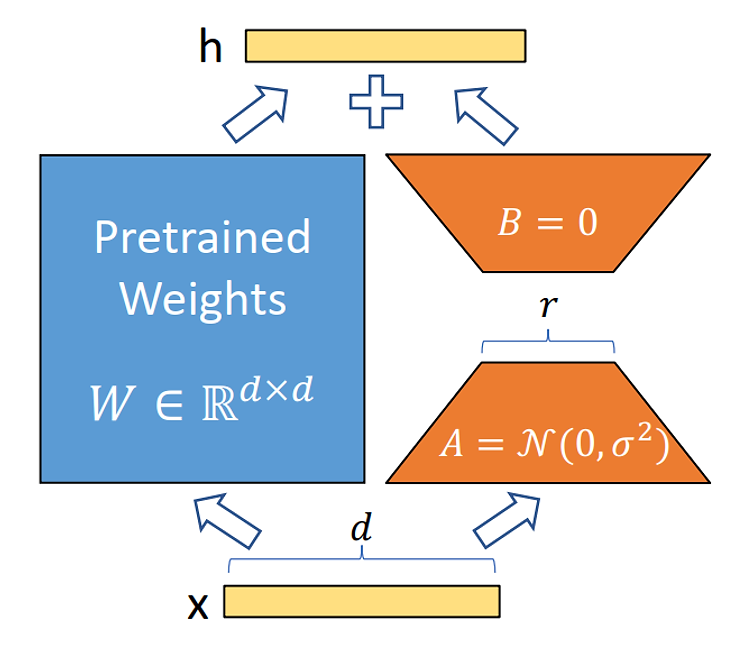
LoRA reparametrization. We only train matrices A and B when fine-tuning LLMs (by Hu et al.)
Challenges and Considerations
While LoRA offers numerous benefits for fine-tuning large language models, it also comes with its own set of challenges. Understanding these challenges and how to address them is crucial for effectively implementing LoRA.
Overfitting and Underfitting:
One of the main challenges when using LoRA is finding the right balance in the complexity of low-rank matrices. If the matrices are too simple, the model might underfit, failing to capture essential information and nuances in the data. Conversely, if the matrices are too complex, the model might overfit, capturing noise along with the relevant data. Achieving the right balance ensures that the model generalizes well to new, unseen data.
Data Heterogeneity:
Another significant challenge is dealing with data heterogeneity. This issue arises when there is a substantial difference between the source domain (where the model was initially trained) and the target domain (where the model is being adapted). Such differences can hinder the model’s ability to transfer knowledge effectively.
Data Availability:
Finally, data availability is a critical consideration. In many cases, obtaining labeled data in the target domain can be challenging and costly. This limitation can impede the fine-tuning process, as LoRA, like other machine learning techniques, generally requires a substantial amount of data to build robust models. Exploring semi-supervised approaches, where the model is trained on a combination of labeled and unlabeled data, can help mitigate this issue.
Future Directions and Research
As LoRA continues to gain traction in the AI community, there are several exciting avenues for future research and development.
Advancements in LoRA Techniques:
One of the primary areas of future research involves exploring new methods to further reduce the number of trainable parameters. While LoRA already significantly decreases the computational load, there is ongoing research to push these boundaries even further. Innovations in matrix factorization techniques and optimization algorithms could lead to even more compact models without sacrificing performance.
Integration with Other Technologies:
Another promising direction for future research is the integration of LoRA with other advanced AI technologies. For instance, combining LoRA with techniques like DreamBooth can enhance model customization, allowing for more personalized and efficient fine-tuning processes.
The future of LoRA is bright, with ongoing research poised to expand its capabilities and applications. As these advancements unfold, LoRA will continue to play a pivotal role in the evolution of AI, enabling more efficient and versatile model adaptation across diverse domains.
Related Articles
- LLM Practitioner’s Guide: Gemma, a Game-Changing Multilingual LLM
- How Multilingual Llama-2 Actually Is?
- The Tango Takes Two: Building Synergy Between AI and Product Management
Want to Fine-Tune an LLM for Your Use Case?
Let's determine the right fine-tuning approach — from LoRA configuration to data strategy — for your specific requirements.