
Fine-Tune Llama 3.1 with SWIFT: Multi-GPU LLM
Unsloth has gained popularity as a library for fine-tuning large language models (LLMs). It significantly reduces both GPU memory usage and training time. We covered Unsloth in detail in our earlier blog post, "How to Fine-Tune Llama 3.1 with Unsloth."
However, Unsloth has its limitations. The most notable one is that it currently supports only single-GPU training.
So, what can you do if single-GPU training is not enough for your project—either because it’s too slow or exceeds the capacity of even the most advanced GPUs? In this post, we introduce SWIFT, a robust alternative to Unsloth that enables efficient multi-GPU training for fine-tuning Llama 3.1.
What is SWIFT?
SWIFT is a cutting-edge library developed by ModelScope for training large language models (LLMs). It supports the full spectrum of tasks: pre-training, fine-tuning, reinforcement learning from human feedback (RLHF), inference, evaluation, and deployment. With SWIFT, you can work seamlessly with over 300 LLMs and more than 50 multimodal large models (MLLMs).
SWIFT goes beyond basic training capabilities by supporting lightweight solutions like Parameter-Efficient Fine-Tuning (PEFT). It also includes a comprehensive Adapters library featuring the latest techniques such as NEFTune, LoRA+, and LLaMA-PRO.
To make the platform accessible even to those new to deep learning, SWIFT offers a user-friendly web interface powered by Gradio. In this blog post, we will guide you through the process of fine-tuning Llama 3.1 using SWIFT on RunPod infrastructure.
Set Up the RunPod Environment
Log in to the RunPod console, navigate to "Pods," and click "Deploy." For this demonstration, we will use the Community Cloud. However, if you have strict security requirements, consider RunPod’s Secure Cloud option.
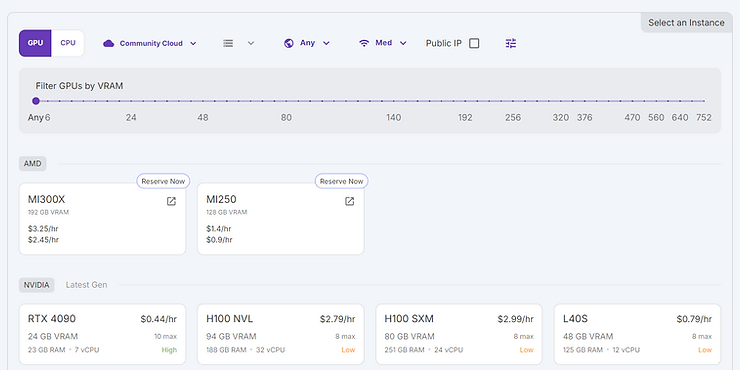
For our example, we will use a multi-GPU instance. We’ll select 2 x RTX A6000 GPUs, as each A6000 offers 48GB of GPU memory—sufficient for most smaller LLMs.
We will use the RunPod PyTorch 2.4.0 image, which is the latest version at the time of writing. To optimize costs, we will use Spot instances.
When working with GPUs, you will need additional storage. RunPod offers two types of storage:
- Container Disk: Temporary storage that is cleared each time you stop the container.
- Volume Disk: Persistent storage that retains data even if the container is restarted or a Spot instance is terminated. Mounted at /workspace by default.
Installing SWIFT
While the official SWIFT documentation suggests a straightforward installation using the PyPI package, if you run it as of September 2024, you will encounter the following error:
Failed to import swift.trainers.trainers because of the following error:
Failed to import modelscope.msdatasets because of the following error:
cannot import name 'ftp_head' from 'datasets.utils.file_utils'
To fix it, install SWIFT by running:
pip install --upgrade --force-reinstall --no-cache-dir \
  git+https://github.com/modelscope/ms-swift.git@88dab2b6625280e813bd8835662e1d2be24a3132
Training Llama 3.1 with SWIFT
Create a new Jupyter Notebook and test your installation:
from swift import Trainer, TrainingArgumentsThen perform the necessary imports:
from swift import Trainer, TrainingArguments
from modelscope import MsDataset, AutoTokenizer
from modelscope import AutoModelForCausalLM
from modelscope import snapshot_download
from swift import Swift, LoraConfig, get_peft_model
from swift.llm import get_template, TemplateType, register_template, Template, TEMPLATE_MAPPING
import torch
import wandb
from datasets import load_dataset
from transformers import BitsAndBytesConfig
from trl import SFTTrainer, DataCollatorForCompletionOnlyLM
Unlike some other frameworks, SWIFT is designed to work with models hosted on ModelScope, not Hugging Face:
model_name = 'LLM-Research/Meta-Llama-3.1-8B-Instruct'
model = AutoModelForCausalLM.from_pretrained(
    model_name, torch_dtype=torch.bfloat16,
    device_map='auto', trust_remote_code=True
)
tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
tokenizer.pad_token_id = 12488
train_set = load_dataset("yahma/alpaca-cleaned", split="train")Processing Training Examples for Consistent Length
SWIFT offers a variety of pre-built LLM prompt templates. Yet, template-based dataset processing does not have default truncation and padding parameters. When using multiple training examples per GPU, all examples must be of the same length.
def create_prompt_formats(sample, test=False):
    result = f"""<|start_header_id|>system<|end_header_id|>

You are a helpful assistant.<|eot_id|><|start_header_id|>user<|end_header_id|>

{sample['instruction']}<|eot_id|><|start_header_id|>assistant<|end_header_id|>

"""
    if not test:
        result += f"""{sample['output']}<|eot_id|>"""
    sample["prompt"] = result
    return sample
def preprocess_batch(batch, tokenizer, max_length, truncation, padding):
return tokenizer(
batch['prompt'],
max_length=max_length,
truncation=truncation,
padding='max_length' if padding else False
)def preprocess_dataset(tokenizer, max_length, seed, dataset, truncation, padding, test):
print("Preprocessing dataset...")
_create_prompt_formats = partial(create_prompt_formats, test=test)
dataset = dataset.map(_create_prompt_formats)
_preprocessing_function = partial(
preprocess_batch, max_length=max_length,
tokenizer=tokenizer, truncation=truncation, padding=padding
)
dataset = dataset.map(_preprocessing_function, batched=True)
dataset = dataset.shuffle(seed=seed)
return datasetTo find the appropriate maximum length, we process the dataset without truncation or padding:
exploration_set = preprocess_dataset(
    tokenizer=tokenizer, max_length=128000, seed=seed,
    dataset=train_set, truncation=False, padding=False, test=False
)

lengths = [len(entry['input_ids']) for entry in exploration_set]
plt.hist(lengths, bins=30, color='blue', edgecolor='black')
plt.title('Histogram of Lengths of input_ids')
plt.xlabel('Length of input_ids')
plt.ylabel('Frequency')
plt.show()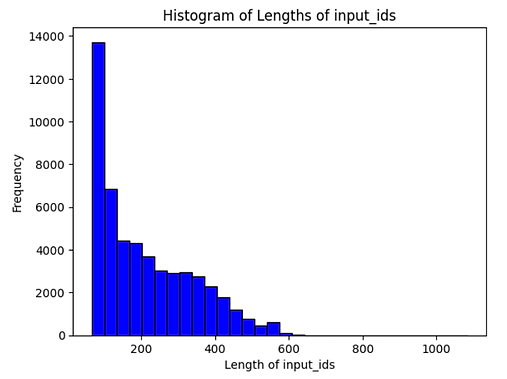
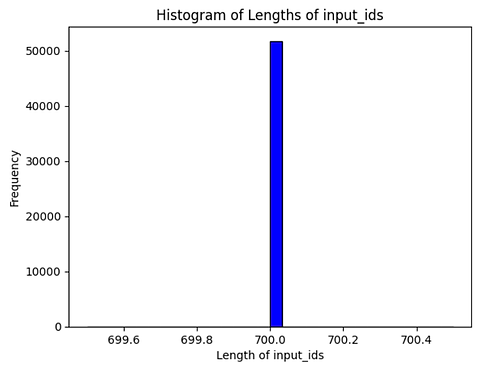
As shown in the histogram, most examples in the Alpaca dataset, after conversion to Llama 3.1 prompt format, are under 700 tokens. We set the maximum length to 700 tokens:
train_set_processed = preprocess_dataset(
    tokenizer=tokenizer, max_length=max_length, seed=seed,
    dataset=train_set, truncation=True, padding=True, test=False
)
Configuring LoRA Parameters
lora_config = LoraConfig(
    r=4,
    target_modules=["q_proj", "k_proj", "v_proj", "o_proj",
                     "gate_proj", "up_proj", "down_proj"],
    lora_alpha=8,
    lora_dropout=0.05
)

model = Swift.prepare_model(model, lora_config)
Setting Up the Data Collator
response_template = "<|start_header_id|>assistant<|end_header_id|>"
collator = DataCollatorForCompletionOnlyLM(response_template, tokenizer=tokenizer)
Defining the Training Configuration
train_args = TrainingArguments(
    output_dir='output',
    learning_rate=1e-4,
    num_train_epochs=2,
    eval_steps=500,
    save_steps=500,
    optim="adamw_8bit",
    fp16=True,
    evaluation_strategy='steps',
    save_strategy='steps',
    log_level="debug",
    dataloader_num_workers=16,
    per_device_train_batch_size=1,
    gradient_accumulation_steps=16,
    logging_steps=1,
)
Initialize the Trainer and Start Training
trainer = Trainer(
    model=model,
    args=train_args,
    train_dataset=train_set_processed,
    tokenizer=tokenizer,
    data_collator=collator
)

trainer.train()
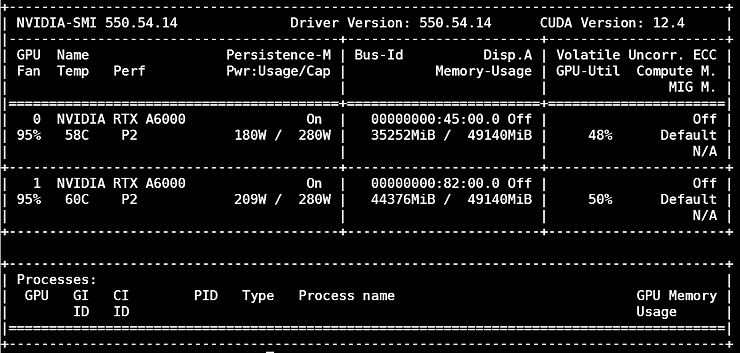
While the training is running, it’s useful to monitor GPU utilization with the nvidia-smi command:
You can find the complete code for this tutorial in our Colab.
Conclusion
Developing your custom LLM could enhance data security and compliance and enable an AI competitive advantage for your product. Check out our related posts:
- How to Fine-Tune Llama 3.1 with Unsloth
- Low-Rank Adaptation (LoRA) for Efficient Fine-Tuning
- Why Do You Need an AI Strategy?
- AI Strategies That Offer a Sustainable Competitive Advantage
Need Multi-GPU Fine-Tuning for Your LLM Project?
Let's design the right training infrastructure and fine-tuning strategy for your custom language model.